
[Oct 30, 2021] Genuine DP-100 Exam Dumps New 2021 Microsoft Pratice Exam
New 2021 Realistic DP-100 Dumps Test Engine Exam Questions in here
Step 3: Taking Online Learning Paths
In addition, Microsoft recommends that the candidates for the DP-100 exam take online courses to adequately prepare for their test. You can find the following learning paths on the official certification webpage:
- Create Machine Learning Models
- Create No-Code Predictive Models with Azure Machine Learning
- Build AI Solutions with Azure Machine Learning
NEW QUESTION 25
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Python script named train.py in a local folder named scripts. The script trains a regression model by using scikit-learn. The script includes code to load a training data file which is also located in the scripts folder.
You must run the script as an Azure ML experiment on a compute cluster named aml-compute.
You need to configure the run to ensure that the environment includes the required packages for model training. You have instantiated a variable named aml-compute that references the target compute cluster.
Solution: Run the following code:
Does the solution meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
The scikit-learn estimator provides a simple way of launching a scikit-learn training job on a compute target. It is implemented through the SKLearn class, which can be used to support single-node CPU training.
Example:
from azureml.train.sklearn import SKLearn
}
estimator = SKLearn(source_directory=project_folder,
compute_target=compute_target,
entry_script='train_iris.py'
)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-train-scikit-learn
NEW QUESTION 26
You are performing a filter based feature selection for a dataset 10 build a multi class classifies by using Azure Machine Learning Studio.
The dataset contains categorical features that are highly correlated to the output label column.
You need to select the appropriate feature scoring statistical method to identify the key predictors. Which method should you use?
- A. Kendall correlation
- B. Person correlation
- C. Spearman correlation
- D. Chi-squared
Answer: D
NEW QUESTION 27
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
- A. Apply a linear discriminant analysis.
- B. Apply a Pearson correlation coefficient.
- C. Apply a Spearman correlation coefficient.
- D. Apply an analysis of variance (ANOVA).
Answer: A
Explanation:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Incorrect Answers:
B: The Pearson correlation coefficient, sometimes called Pearson's R test, is a statistical value that measures the linear relationship between two variables. By examining the coefficient values, you can infer something about the strength of the relationship between the two variables, and whether they are positively correlated or negatively correlated.
C: Spearman's correlation coefficient is designed for use with non-parametric and non-normally distributed data. Spearman's coefficient is a nonparametric measure of statistical dependence between two variables, and is sometimes denoted by the Greek letter rho. The Spearman's coefficient expresses the degree to which two variables are monotonically related. It is also called Spearman rank correlation, because it can be used with ordinal variables.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/fisher-linear-discriminant- analysis
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-linear-correlation Perform Feature Engineering Testlet 2 Case study This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities.
You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris. You add both files to Azure Machine Learning Studio as separate datasets to the starting point for an experiment. Both datasets contain the following columns:
An initial investigation shows that the datasets are identical in structure apart from the MedianValue column.
The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format.
Data issues
Missing values
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The datasets also contain many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsInHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance. In each case, the predictor of the dataset is the column named MedianValue. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parametric statistics to measure relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsInHouse columns.
Model training
Permutation Feature Importance
Given a trained model and a test dataset, you must compute the Permutation Feature Importance scores of feature variables. You must be determined the absolute fit for the model.
Hyperparameters
You must configure hyperparameters in the model learning process to speed the learning phase. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, must implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio.
Cross-validation
You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. You must complete this task before the data goes through the sampling process.
Linear regression module
When you train a Linear Regression module, you must determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. The distribution of features across multiple training models must be consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
NEW QUESTION 28
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a model to predict the price of a student's artwork depending on the following variables: the student's length of education, degree type, and art form.
You start by creating a linear regression model.
You need to evaluate the linear regression model.
Solution: Use the following metrics: Accuracy, Precision, Recall, F1 score and AUC.
Does the solution meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
Explanation
Those are metrics for evaluating classification models, instead use: Mean Absolute Error, Root Mean Absolute Error, Relative Absolute Error, Relative Squared Error, and the Coefficient of Determination.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
NEW QUESTION 29
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are analyzing a numerical dataset which contains missing values in several columns.
You must clean the missing values using an appropriate operation without affecting the dimensionality of the feature set.
You need to analyze a full dataset to include all values.
Solution: Calculate the column median value and use the median value as the replacement for any missing value in the column.
Does the solution meet the goal?
- A. No
- B. Yes
Answer: A
Explanation:
Explanation
Use the Multiple Imputation by Chained Equations (MICE) method.
References:
https://www.ncbi.nlm.nih.gov/pmc/articles/PMC3074241/
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data
NEW QUESTION 30
You train a classification model by using a decision tree algorithm.
You create an estimator by running the following Python code. The variable feature_names is a list of all feature names, and class_names is a list of all class names.
from interpret.ext.blackbox import TabularExplainer
You need to explain the predictions made by the model for all classes by determining the importance of all features.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Yes
TabularExplainer calls one of the three SHAP explainers underneath (TreeExplainer, DeepExplainer, or KernelExplainer).
Box 2: Yes
To make your explanations and visualizations more informative, you can choose to pass in feature names and output class names if doing classification.
Box 3: No
TabularExplainer automatically selects the most appropriate one for your use case, but you can call each of its three underlying explainers underneath (TreeExplainer, DeepExplainer, or KernelExplainer) directly.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-interpretability-aml
NEW QUESTION 31
You must store data in Azure Blob Storage to support Azure Machine Learning.
You need to transfer the data into Azure Blob Storage.
What are three possible ways to achieve the goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
- A. AzCopy
- B. Python script
- C. Bulk Insert SQL Query
- D. Bulk Copy Program (BCP)
- E. Azure Storage Explorer
Answer: A,B,E
Explanation:
Explanation
You can move data to and from Azure Blob storage using different technologies:
Azure Storage-Explorer
AzCopy
Python
SSIS
References:
https://docs.microsoft.com/en-us/azure/machine-learning/team-data-science-process/move-azure-blob
NEW QUESTION 32
You have a dataset that contains over 150 features. You use the dataset to train a Support Vector Machine (SVM) binary classifier.
You need to use the Permutation Feature Importance module in Azure Machine Learning Studio to compute a set of feature importance scores for the dataset.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
1 - Add a Two-Class Support Vector Machine module to initialize the SVM classifier.
2 - Add a dataset to the experiment
3 - Add a Split Data module to create training and test dataset.
4 - Add a Permutation Feature Importance module and connect to the trained model and test dataset.
5 - Set the Metric for measuring performance property to Classification - Accuracy and then run the experiment.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine
https:HYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"//docs.microsoft.com/en-us/aHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"zure/machine-learning/studio-module-reference/two-class-support-vector-machine https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
https:HYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"//docs.microsoft.com/en-us/aHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/two-class-support-vector-machine"zure/machine-learning/studio-module-reference/two-class-support-vector-machine https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
https://docs.microsoHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ft.com/en-us/azure/machine-learnHYPERLINK "https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/permutation-feature-importance"ing/studio-module-reference/permutation-feature-importance
NEW QUESTION 33
You need to visually identify whether outliers exist in the Age column and quantify the outliers before the outliers are removed.
Which three Azure Machine Learning Studio modules should you use in sequence? To answer, move the appropriate modules from the list of modules to the answer area and arrange them in the correct order.
Answer:
Explanation:
NEW QUESTION 34
Your team is building a data engineering and data science development environment.
The environment must support the following requirements:
support Python and Scala
compose data storage, movement, and processing services into automated data pipelines
the same tool should be used for the orchestration of both data engineering and data science
support workload isolation and interactive workloads
enable scaling across a cluster of machines
You need to create the environment.
What should you do?
- A. Build the environment in Azure Databricks and use Azure Container Instances for orchestration.
- B. Build the environment in Apache Spark for HDInsight and use Azure Container Instances for orchestration.
- C. Build the environment in Apache Hive for HDInsight and use Azure Data Factory for orchestration.
- D. Build the environment in Azure Databricks and use Azure Data Factory for orchestration.
Answer: D
Explanation:
Explanation/Reference:
Explanation:
In Azure Databricks, we can create two different types of clusters.
Standard, these are the default clusters and can be used with Python, R, Scala and SQL
High-concurrency
Azure Databricks is fully integrated with Azure Data Factory.
Incorrect Answers:
D: Azure Container Instances is good for development or testing. Not suitable for production workloads.
References:
https://docs.microsoft.com/en-us/azure/architecture/data-guide/technology-choices/data-science-and- machine-learning
NEW QUESTION 35
You are analyzing a dataset containing historical data from a local taxi company. You arc developing a regression a regression model.
You must predict the fare of a taxi trip.
You need to select performance metrics to correctly evaluate the- regression model.
Which two metrics can you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
- A. an R-Squared value close to 0
- B. an F1 score that is high
- C. a Root Mean Square Error value that is high
- D. a Root Mean Square Error value that is low
- E. an F 1 score that is low.
- F. an R Squared value dose to 1
Answer: D,F
Explanation:
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/evaluate-model
NEW QUESTION 36
You have a multi-class image classification deep learning model that uses a set of labeled photographs. You create the following code to select hyperparameter values when training the model.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Yes
Hyperparameters are adjustable parameters you choose to train a model that govern the training process itself. Azure Machine Learning allows you to automate hyperparameter exploration in an efficient manner, saving you significant time and resources. You specify the range of hyperparameter values and a maximum number of training runs. The system then automatically launches multiple simultaneous runs with different parameter configurations and finds the configuration that results in the best performance, measured by the metric you choose. Poorly performing training runs are automatically early terminated, reducing wastage of compute resources. These resources are instead used to explore other hyperparameter configurations.
Box 2: Yes
uniform(low, high) - Returns a value uniformly distributed between low and high Box 3: No Bayesian sampling does not currently support any early termination policy.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
NEW QUESTION 37
You need to implement early stopping criteria as suited in the model training requirements.
Which three code segments should you use to develop the solution? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
Answer:
Explanation:
Explanation
You need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Truncation selection cancels a given percentage of lowest performing runs at each evaluation interval. Runs are compared based on their performance on the primary metric and the lowest X% are terminated.
Example:
from azureml.train.hyperdrive import TruncationSelectionPolicy
early_termination_policy = TruncationSelectionPolicy(evaluation_interval=1, truncation_percentage=20, delay_evaluation=5)
NEW QUESTION 38
Your team is building a data engineering and data science development environment.
The environment must support the following requirements:
support Python and Scala
compose data storage, movement, and processing services into automated data pipelines the same tool should be used for the orchestration of both data engineering and data science support workload isolation and interactive workloads enable scaling across a cluster of machines You need to create the environment.
What should you do?
- A. Build the environment in Azure Databricks and use Azure Container Instances for orchestration.
- B. Build the environment in Apache Spark for HDInsight and use Azure Container Instances for orchestration.
- C. Build the environment in Apache Hive for HDInsight and use Azure Data Factory for orchestration.
- D. Build the environment in Azure Databricks and use Azure Data Factory for orchestration.
Answer: D
Explanation:
In Azure Databricks, we can create two different types of clusters.
* Standard, these are the default clusters and can be used with Python, R, Scala and SQL
* High-concurrency
Azure Databricks is fully integrated with Azure Data Factory.
Incorrect Answers:
D: Azure Container Instances is good for development or testing. Not suitable for production workloads.
References:
https://docs.microsoft.com/en-us/azure/architecture/data-guide/technology-choices/data-science-and-machinelearning
NEW QUESTION 39
You plan to explore demographic data for home ownership in various cities. The data is in a CSV file with the following format:
age,city,income,home_owner
21,Chicago,50000,0
35,Seattle,120000,1
23,Seattle,65000,0
45,Seattle,130000,1
18,Chicago,48000,0
You need to run an experiment in your Azure Machine Learning workspace to explore the data and log the results. The experiment must log the following information:
* the number of observations in the dataset
* a box plot of income by home_owner
* a dictionary containing the city names and the average income for each city You need to use the appropriate logging methods of the experiment's run object to log the required information.
How should you complete the code? To answer, drag the appropriate code segments to the correct locations. Each code segment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.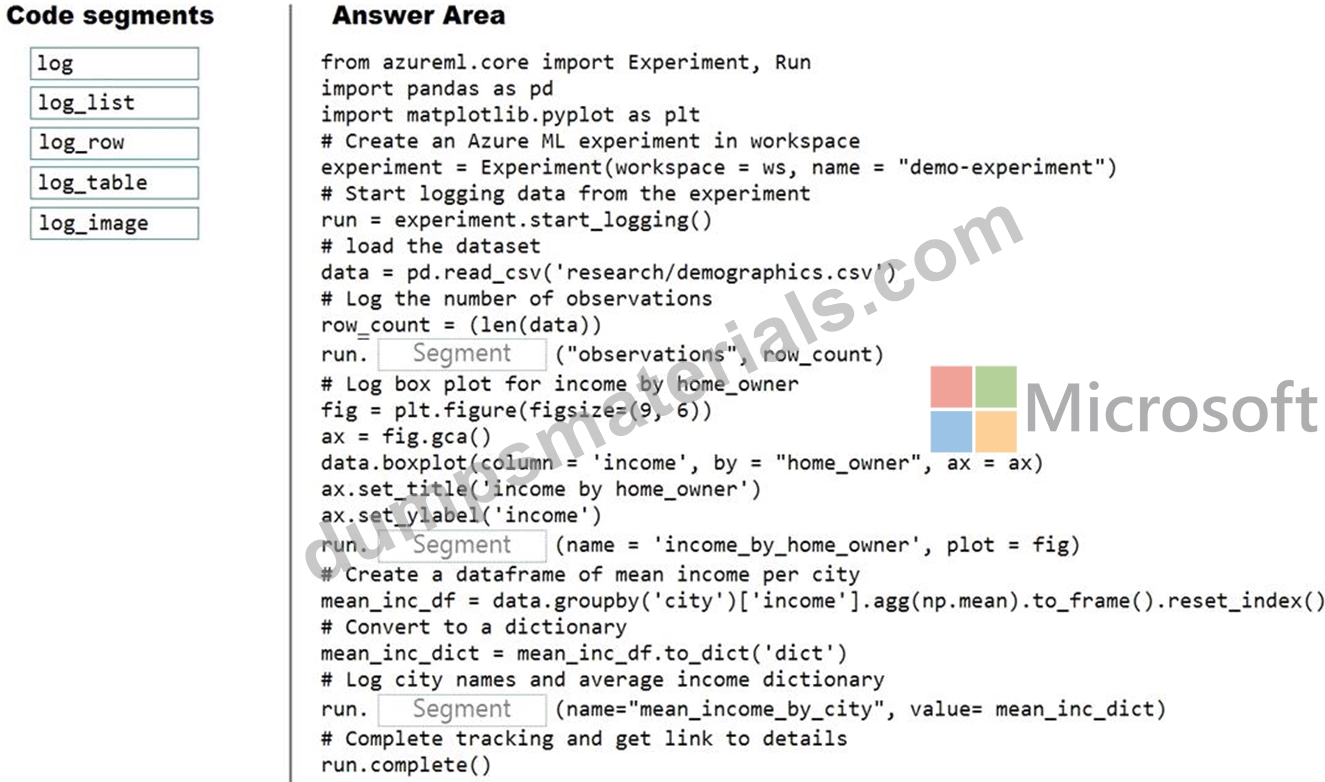
Answer:
Explanation:
Explanation:
Box 1: log
The number of observations in the dataset.
run.log(name, value, description='')
Scalar values: Log a numerical or string value to the run with the given name. Logging a metric to a run causes that metric to be stored in the run record in the experiment. You can log the same metric multiple times within a run, the result being considered a vector of that metric.
Example: run.log("accuracy", 0.95)
Box 2: log_image
A box plot of income by home_owner.
log_image Log an image to the run record. Use log_image to log a .PNG image file or a matplotlib plot to the run. These images will be visible and comparable in the run record.
Example: run.log_image("ROC", plot=plt)
Box 3: log_table
A dictionary containing the city names and the average income for each city.
log_table: Log a dictionary object to the run with the given name.
NEW QUESTION 40
You need to select a feature extraction method.
Which method should you use?
- A. Permutation Feature Importance
- B. Mood's median test
- C. Mutual information
- D. Kendall correlation
Answer: D
Explanation:
Explanation/Reference:
Explanation:
In statistics, the Kendall rank correlation coefficient, commonly referred to as Kendall's tau coefficient (after the Greek letter τ), is a statistic used to measure the ordinal association between two measured quantities.
It is a supported method of the Azure Machine Learning Feature selection.
Scenario: When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/feature-selection- modules Question Set 3
NEW QUESTION 41
You plan to use the Hyperdrive feature of Azure Machine Learning to determine the optimal hyperparameter values when training a model.
You must use Hyperdrive to try combinations of the following hyperparameter values:
* learning_rate: any value between 0.001 and 0.1
* batch_size: 16, 32, or 64
You need to configure the search space for the Hyperdrive experiment.
Which two parameter expressions should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. a choice expression for batch_size
- B. a uniform expression for learning_rate
- C. a normal expression for batch_size
- D. a uniform expression for batch_size
- E. a choice expression for learning_rate
Answer: A,B
Explanation:
B: Continuous hyperparameters are specified as a distribution over a continuous range of values. Supported distributions include:
* uniform(low, high) - Returns a value uniformly distributed between low and high D: Discrete hyperparameters are specified as a choice among discrete values. choice can be:
* one or more comma-separated values
* a range object
* any arbitrary list object
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-tune-hyperparameters
NEW QUESTION 42
You need to implement a new cost factor scenario for the ad response models as illustrated in the performance curve exhibit.
Which technique should you use?
- A. Set the threshold to 0.2 and retrain if weighted Kappa deviates +/- 5% from 0.6.
- B. Set the threshold to 0.5 and retrain if weighted Kappa deviates +/- 5% from 0.45.
- C. Set the threshold to 0.75 and retrain if weighted Kappa deviates +/- 5% from 0.15.
- D. Set the threshold to 0.05 and retrain if weighted Kappa deviates +/- 5% from 0.5.
Answer: B
Explanation:
Explanation/Reference:
Explanation:
Scenario:
Performance curves of current and proposed cost factor scenarios are shown in the following diagram:
The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from
0.1 +/- 5%.
NEW QUESTION 43
You need to implement early stopping criteria as suited in the model training requirements.
Which three code segments should you use to develop the solution? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
Answer:
Explanation: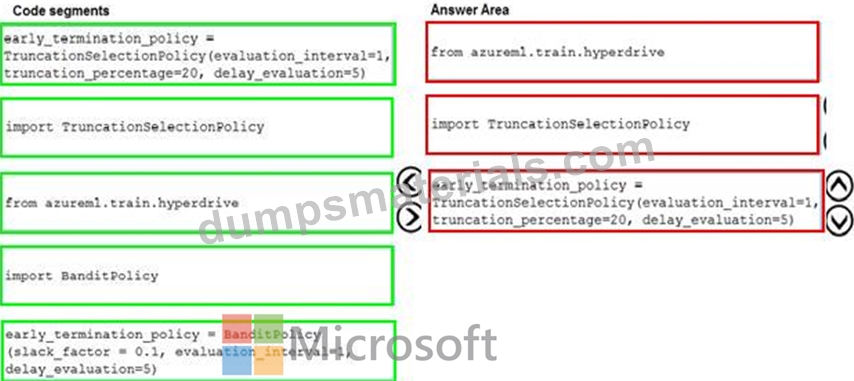
Explanation:
You need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Truncation selection cancels a given percentage of lowest performing runs at each evaluation interval. Runs are compared based on their performance on the primary metric and the lowest X% are terminated.
Example:
from azureml.train.hyperdrive import TruncationSelectionPolicy
early_termination_policy = TruncationSelectionPolicy(evaluation_interval=1, truncation_percentage=20, delay_evaluation=5) Incorrect Answers:
Bandit is a termination policy based on slack factor/slack amount and evaluation interval. The policy early terminates any runs where the primary metric is not within the specified slack factor / slack amount with respect to the best performing training run.
Example:
from azureml.train.hyperdrive import BanditPolicy
early_termination_policy = BanditPolicy(slack_factor = 0.1, evaluation_interval=1, delay_evaluation=5 References:
https://docs.microsoft.com/en-us/azure/machine-learning/service/how-to-tune-hyperparameters
NEW QUESTION 44
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1 .csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2,l
1,1,2,0
2,1,1,1
3.2.1.0
You run the following code:
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code:
Does the solution meet the goal?
- A. No
- B. Yes
Answer: B
Explanation:
Explanation
Use two file paths.
Use Dataset.Tabular_from_delimeted as the data isn't cleansed.
Note:
A TabularDataset represents data in a tabular format by parsing the provided file or list of files. This provides you with the ability to materialize the data into a pandas or Spark DataFrame so you can work with familiar data preparation and training libraries without having to leave your notebook. You can create a TabularDataset object from .csv, .tsv, .parquet, .jsonl files, and from SQL query results.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION 45
You are running a training experiment on remote compute in Azure Machine Learning.
The experiment is configured to use a conda environment that includes the mlflow and azureml-contrib-run packages.
You must use MLflow as the logging package for tracking metrics generated in the experiment You need to complete the script for the experiment How should you complete the code? To answer, select the appropriate options in the answer area.
Answer:
Explanation:
NEW QUESTION 46
You use Azure Machine Learning to train and register a model.
You must deploy the model into production as a real-time web service to an inference cluster named service-compute that the IT department has created in the Azure Machine Learning workspace.
Client applications consuming the deployed web service must be authenticated based on their Azure Active Directory service principal.
You need to write a script that uses the Azure Machine Learning SDK to deploy the model. The necessary modules have been imported.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation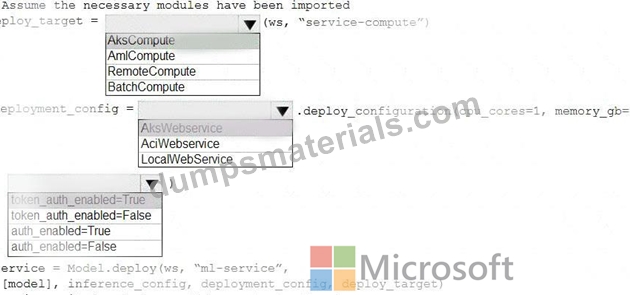
Box 1: AksCompute
Example:
aks_target = AksCompute(ws,"myaks")
# If deploying to a cluster configured for dev/test, ensure that it was created with enough
# cores and memory to handle this deployment configuration. Note that memory is also used by
# things such as dependencies and AML components.
deployment_config = AksWebservice.deploy_configuration(cpu_cores = 1, memory_gb = 1) service = Model.deploy(ws, "myservice", [model], inference_config, deployment_config, aks_target) Box 2: AksWebservice Box 3: token_auth_enabled=Yes Whether or not token auth is enabled for the Webservice.
Note: A Service principal defined in Azure Active Directory (Azure AD) can act as a principal on which authentication and authorization policies can be enforced in Azure Databricks.
The Azure Active Directory Authentication Library (ADAL) can be used to programmatically get an Azure AD access token for a user.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-deploy-azure-kubernetes-service
https://docs.microsoft.com/en-us/azure/databricks/dev-tools/api/latest/aad/service-prin-aad-token
NEW QUESTION 47
You need to implement early stopping criteria as suited in the model training requirements.
Which three code segments should you use to develop the solution? To answer, move the appropriate code segments from the list of code segments to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
Answer:
Explanation:
Explanation
You need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Truncation selection cancels a given percentage of lowest performing runs at each evaluation interval. Runs are compared based on their performance on the primary metric and the lowest X% are terminated.
Example:
from azureml.train.hyperdrive import TruncationSelectionPolicy
early_termination_policy = TruncationSelectionPolicy(evaluation_interval=1, truncation_percentage=20, delay_evaluation=5)
NEW QUESTION 48
You are using a decision tree algorithm. You have trained a model that generalizes well at a tree depth equal to 10.
You need to select the bias and variance properties of the model with varying tree depth values.
Which properties should you select for each tree depth? To answer, select the appropriate options in the answer area.
Answer:
Explanation:
References:
https://machinelearningmastery.com/gentle-introduction-to-the-bias-variance-trade-off-in-machine-learning/
NEW QUESTION 49
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation
Step 1: Define a cross-entropy function activation
When using a neural network to perform classification and prediction, it is usually better to use cross-entropy error than classification error, and somewhat better to use cross-entropy error than mean squared error to evaluate the quality of the neural network.
Step 2: Add cost functions for each target state.
Step 3: Evaluated the distance error metric.
References:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
NEW QUESTION 50
......
DP-100 Exam topics
Candidates must know the exam topics before they start of preparation. Because it will really help them in hitting the core. Our DP-100 dumps will include the following topics:
- Develop models 40-45%
- Prepare data for modeling 25-30%
- Perform feature engineering 15-20%
- Define and prepare the development environment 15-20%
What Next after This Certification?
The certification obtained from passing DP-100 exam is proof of intermediate skills in data science since it is within the associate hierarchy. Apart from applying for and getting a job in a preferred company, you can also expand your skills in an area of interest. With the role-based scheme, there are expert certifications awaiting you to earn. They include the Microsoft Certified: Azure Solutions Architect Expert and the Microsoft Certified: Azure DevOps Engineer Expert.
Grab latest Amazon DP-100 Dumps as PDF Updated: https://www.dumpsmaterials.com/DP-100-real-torrent.html
Updated Official licence for DP-100 Certified by DP-100 Dumps PDF: https://drive.google.com/open?id=1Yl7A-JCDy5m6oU2TKBuMcEeZB9zQxSF1
